Clean, tested data pipelines behind your BI and AI

Dashboards lie and AI hallucinates when the underlying tables are messy. We build monitored CDC pipelines, medallion dbt models and clean evaluation datasets across BigQuery, Snowflake, AWS and Postgres.

Data engineering medallion pipeline drawing: raw events from Postgres CDC, Stripe, CRM and Ads flow through Bronze ingestion, Silver dbt cleaning and quality gates into Gold semantic tables for BI, Reverse-ETL and AI RAG medallion.pipeline.blueprint ingest · dbt · quality · activate PRODUCT DB CDCPostgres / MySQL CRM & BILLINGHubSpot · Stripe AD PLATFORMSGoogle · Meta · TikTok WAREHOUSE + DBT TRANSFORMATION & QUALITY GATES BRONZE · RAWimmutable SILVER · CLEANdedup + PII mask GOLD · MARTS214 tests pass ✓ EXECUTIVE BICEO scorecardCohort LTV AI / RAG CORPUSPermissioned chunksEval datasets REVERSE ETLScores → CRMEvents → CAPI FRESHNESS, VOLUME & SCHEMA MONITORED 24/7 Alerts the data owner before a broken table reaches a dashboard or model

WHAT WE BUILD WITH DATA ENGINEERING

Six data systems that end spreadsheet chaos and power AI

We connect your scattered software tools into one clean, tested data warehouse so leadership trusts the numbers and your AI assistants read accurate data.

Join CRM, ERP, billing and ad spend in one clean warehouse BigQuery · Snowflake · Postgres · dbt
UNIFIED: CRM + ERP + Stripe + Google/Meta Ads VERIFIED: 214 automated dbt quality checks pass daily
Single Source of Truth Warehouse

Join CRM, ERP, billing and ad spend in one clean warehouse

End the Monday argument over whose Excel sheet is right. We unify Stripe, SAP/Logo/NetSuite, HubSpot and ad platforms into reconciled dbt tables.

Build our data warehouse
Replace fragile cron jobs and manual CSV exports CDC · Airbyte · AWS Glue · PySpark
PIPELINE: Postgres CDC + 12 SaaS connectors FRESHNESS: Updated every 5 minutes · Zero manual CSVs
Automated ETL & Real-Time Sync

Replace fragile cron jobs and manual CSV exports

We build monitored, idempotent pipelines that stream database changes (CDC) and API events in minutes, alerting Slack immediately if an upstream API changes.

Automate our data pipelines
Turn messy PDFs, tickets and tables into AI-ready datasets Chunking · OCR · Deduplication · Vector DB
CORPUS: 45,000 PDFs & support tickets cleaned INDEXED: Permission-tagged in Qdrant / pgvector
Clean Data & Document Prep for AI

Turn messy PDFs, tickets and tables into AI-ready datasets

AI is only as smart as the data you feed it. Our data engineers and supervised data interns clean, deduplicate, label and index your documents for RAG and ML.

Prepare our data for AI
Push warehouse scores and LTV back into your sales & ad tools HubSpot · Salesforce · Meta CAPI · Google
SYNCED: Product usage & LTV pushed to HubSpot ADS LIFT: Meta & Google bidding on real margin
Reverse-ETL into CRM & Ad Platforms

Push warehouse scores and LTV back into your sales & ad tools

Sync product usage, churn risk and real closed-won revenue from your warehouse straight into HubSpot and ad pixels so algorithms bid on real buyers.

Sync warehouse to CRM & ads
Cut your monthly cloud warehouse bill by 30 to 60% Partitioning · Clustering · Query Refactor
BEFORE: $6,800/mo warehouse bill · 45s dashboard load AFTER: $2,600/mo (−61%) · 1.8s dashboard load
BigQuery & Snowflake Cost Reduction

Cut your monthly cloud warehouse bill by 30 to 60%

Full-table scans and unpartitioned dbt models silently burn thousands of dollars. We partition, cluster and refactor slow queries in a 3-week sprint.

Cut our warehouse bill
Offload ongoing data cleaning, migration and annotation Senior Data Engineer + Trained Interns
CAPACITY: Senior architect + data operations pod OUTPUT: Clean, documented, schema-validated tables
Managed Data Cleaning & Labeling Pod

Offload ongoing data cleaning, migration and annotation

Need thousands of product rows, messy legacy ERP tables or training samples cleaned and verified? Our supervised data pod handles the heavy lifting.

Hire a data cleaning pod

INTERACTIVE LINEAGE DAG

Click any node in the pipeline to inspect its SQL contract and quality gate

Latency < 60s · Idempotent

CDC & Webhook Ingest

Capture row-level changes from Postgres/MySQL (Debezium/CDC) alongside Stripe, HubSpot and ad platform webhooks without impacting production database load.

-- CDC Stream Contract
source: postgres_wal_stream (slot: orzed_cdc)
deduplication_key: (event_id, lsn_offset)
on_schema_drift: alert_slack("#data-ops") + quarantine_extra_cols
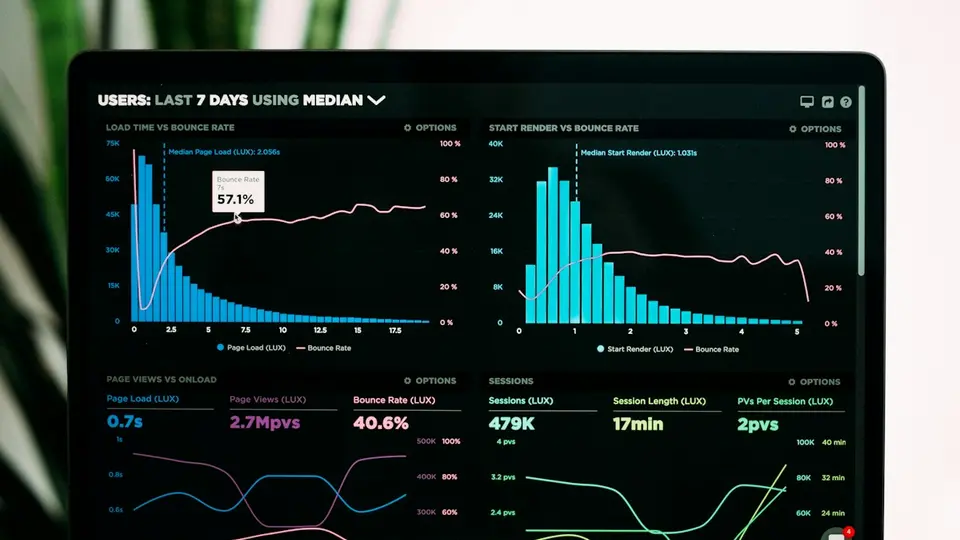
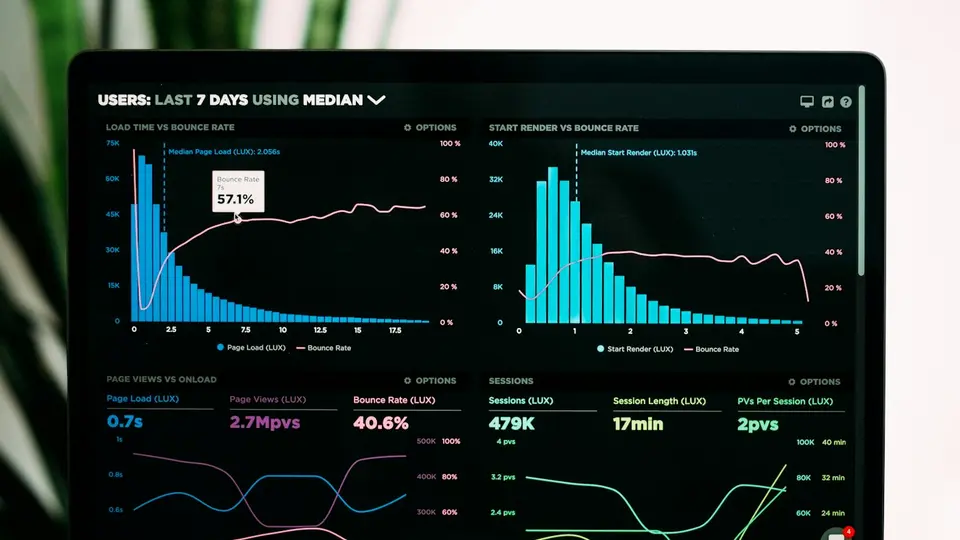
Live data pipeline telemetry and query latency graphs
Senior engineer + data intern pod Senior engineers design the schema; trained data interns handle cleaning, labeling and QA
Warehouse bill creeping up?

Cut BigQuery or Snowflake compute spend by 30 to 60%

We refactor unpartitioned queries, add clustering keys and prune dead dbt models in a focused three-week sprint.

WHAT WE BUILD

Four layers of a modern data stack

01

Reliable data pipelines and connectors

Ads, CRM, billing, ERP and product databases synced automatically.

We replace fragile cron scripts and manual CSV exports with monitored pipelines (Airbyte, Fivetran, Kafka, AWS Kinesis/Glue or custom Python/PySpark workers) that alert Slack the moment a source drifts.

CDC & webhooksAirflow / Dagster / GluePySparkSchema-drift alerts
Fix my data pipelines
02

Warehouse architecture and dbt modeling

BigQuery, Snowflake, ClickHouse or Postgres modeled cleanly in dbt.

We structure raw, staging and mart layers in dbt with automated data-quality tests, documentation and partitioning/clustering so queries stay fast and warehouse bills drop by 30 to 60%.

BigQuery / SnowflakePostgres / ClickHousedbt core + testsQuery cost control
Design our warehouse
03

AI, RAG and evaluation dataset pipelines

Good AI starts with clean, permissioned, deduplicated data.

With our senior data engineers and supervised data interns, we build document chunking, metadata tagging, embedding refresh and 500-case evaluation sets that keep your AI accurate.

RAG indexingpgvector / Qdrant / ChromaEval dataset prepPII redaction
Prepare data for AI
04

Reverse ETL and operational activation

Push clean scores and segments back into HubSpot, Klaviyo and ad platforms.

A warehouse should not be a dead end. We sync product usage, health scores and LTV back into your CRM and ad platforms so sales and marketing act on live data.

Reverse ETLProduct-qualified leadsServer-side CAPICRM enrichment
Sync warehouse to CRM
2.4BEvents ingested per day
90sFreshness p95, core marts
14Connectors healthy
Throughput and freshness across pipeline releases
  • INGESTkafka lag zero2.4B/day
  • CONTRACTschema v12 accepted0 breaks
  • DBT214 models green6m run
  • COSTpartition prune−$2.8k/mo
  • DQnull rate 0.02%pass

WAYS TO START

Stand up the warehouse or add a monthly data pod

Start clean

Warehouse & Pipeline Foundation

Stand up a clean warehouse with your top 4 data sources and core dbt models.

3 to 4 weeks
  • BigQuery, Snowflake or Postgres setup
  • 4 sources connected (CRM, Ads, Billing, DB)
  • Core dbt models + quality tests
  • Documentation & cost guardrails
Build our data foundation ↗
AI & BI ready

Production Data + AI Corpus Pipeline

End-to-end data platform powering both executive BI and grounded AI assistants.

6 to 10 weeks
  • Full medallion dbt architecture
  • PII redaction & permission boundaries
  • RAG / vector indexing pipeline
  • Reverse-ETL sync back to CRM
Scope a data platform ↗
Ongoing

Data Engineering Pod

A senior data engineer + data intern maintaining pipelines, cleaning datasets and cutting warehouse spend.

Monthly
  • New connectors & dbt models
  • Dataset cleaning, labeling & QA
  • Warehouse query cost optimization
  • Pipeline monitoring & SLA care
Add a data pod ↗

Adjacent disciplines

Ingest · Model · Activate

Ready for data pipelines thatnever silently break?

Tell us your current sources and warehouse. We reply with an architecture plan and fixed scope within one business day.